Repository navigation
Releases
v0.9.77: Reliable setup, extension updates, and faster browsing

Changes since v0.9.76
A small follow-up release with fixes found while checking fresh installations and live captures.
- 🛠️ More reliable setup and installs. Server settings stay saved when captures start, and Debian installations correctly install capture tools under the collection owner.
- 🌐 Chrome extensions update properly. Existing installations can pick up newer extension versions instead of getting stuck on an older cached copy.
- ⚡ Faster browsing of large collections. Snapshot and output API requests avoid repeatedly loading large crawl inputs and related records.
- 📦 Updated capture tools. Includes the latest tested downloader and plugin packages, including upstream SingleFile improvements.
See v0.9.76 for AI-powered social imports, chat bots, smoother replay, and screenshots of the new interfaces.
v0.9.76: Automatic import from social media, new Slack bot, and way faster archiving
Highlights
Automatic social media archiving, chat bots, smoother mobile replay, and faster archiving @ ~1min/URL.
- 🤖 NEW Automatic social media importing! Back up posts, bookmarks, likes, photos, and more from X, Facebook, Instagram, Reddit, and other sites, alongside RSS feeds and spreadsheets. The new autoresearch-based engine uses AI to create a custom importer for your data and automatically heal it when the site changes. After that scheduled imports run the saved script without any AI. Connect your logged-in browser through a Persona, preview what will be saved, and schedule automatic imports.

- 💬 Save links straight from your chats. The optional ArchiveBox Chat Bot brings archiving to Slack, Telegram, WhatsApp, Zulip, and more. Send links in a DM, mention the bot in a thread, or ask ArchiveBox AI Bot to organize and archive a collection for you.
- ⚡️ Faster archiving and replay. Archiving has been highly optimized for slower hard drives and servers, it can average 1min/URL consistently now even with >5,000 queued tasks and limited memory and CPU.
- 🖼️ More complete saved pages. Fixes restore missing styles, images, backgrounds, and redirected resources during replay. Improved file browsing makes it easier to explore and download everything saved with a page.

- 🕰️ Memento API support. New Memento support lets compatible tools find the saved version closest to a date and discover other captures of the same URL.
- 🔐 Privacy and security fixes. Stronger protections keep private captures, browser cookies, and server files out of public replay and downloads. Thanks to Yves Soete of Blacksight LLC for reporting security issues.
v0.9.73: Google Docs, Drive & Dropbox archiving, mobile replay, and faster archives
Changes since v0.9.71
Four new plugins for cloud documents, shared folders, and better mobile replay — plus faster large archives and a more useful file browser.
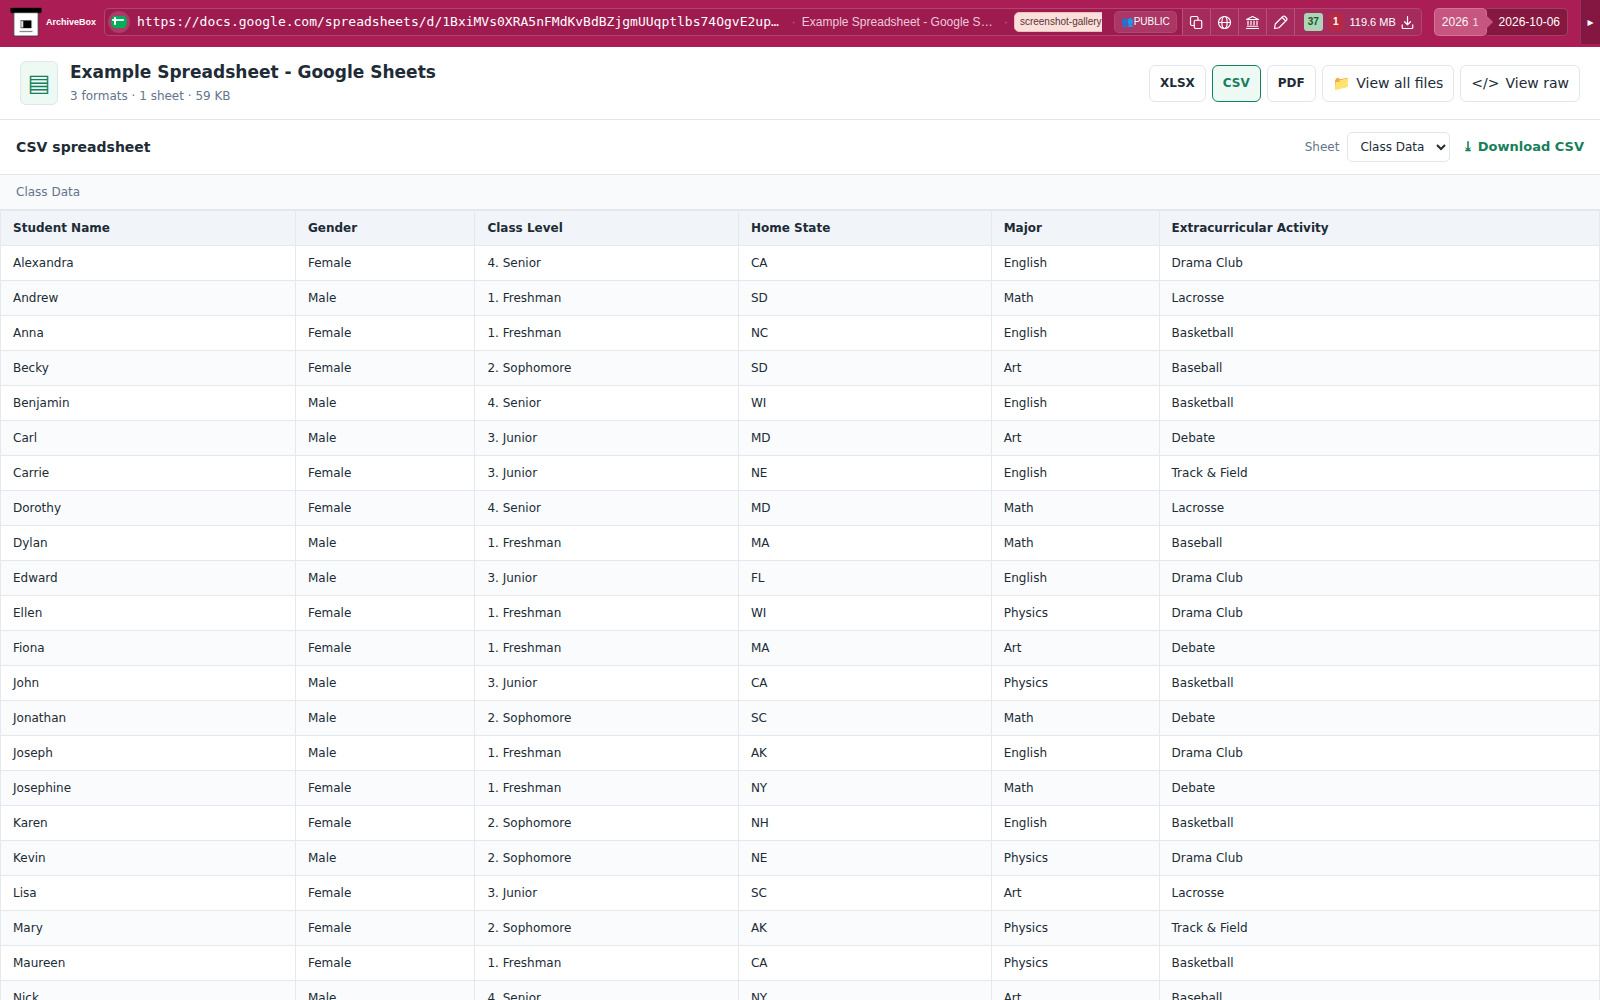
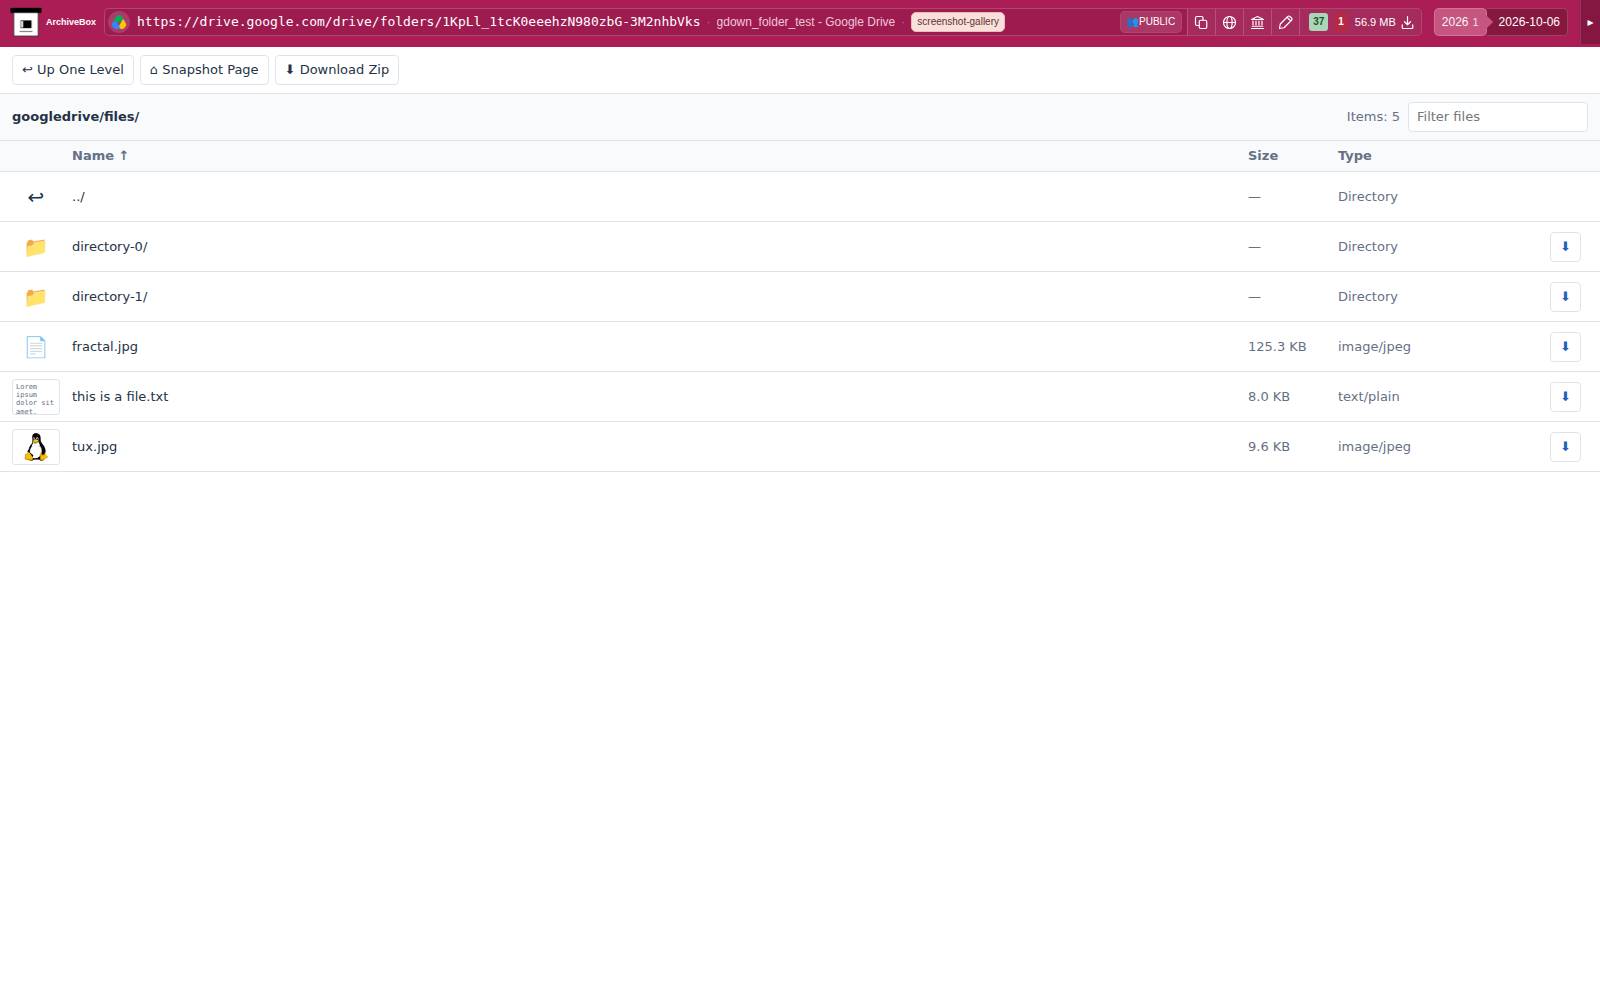
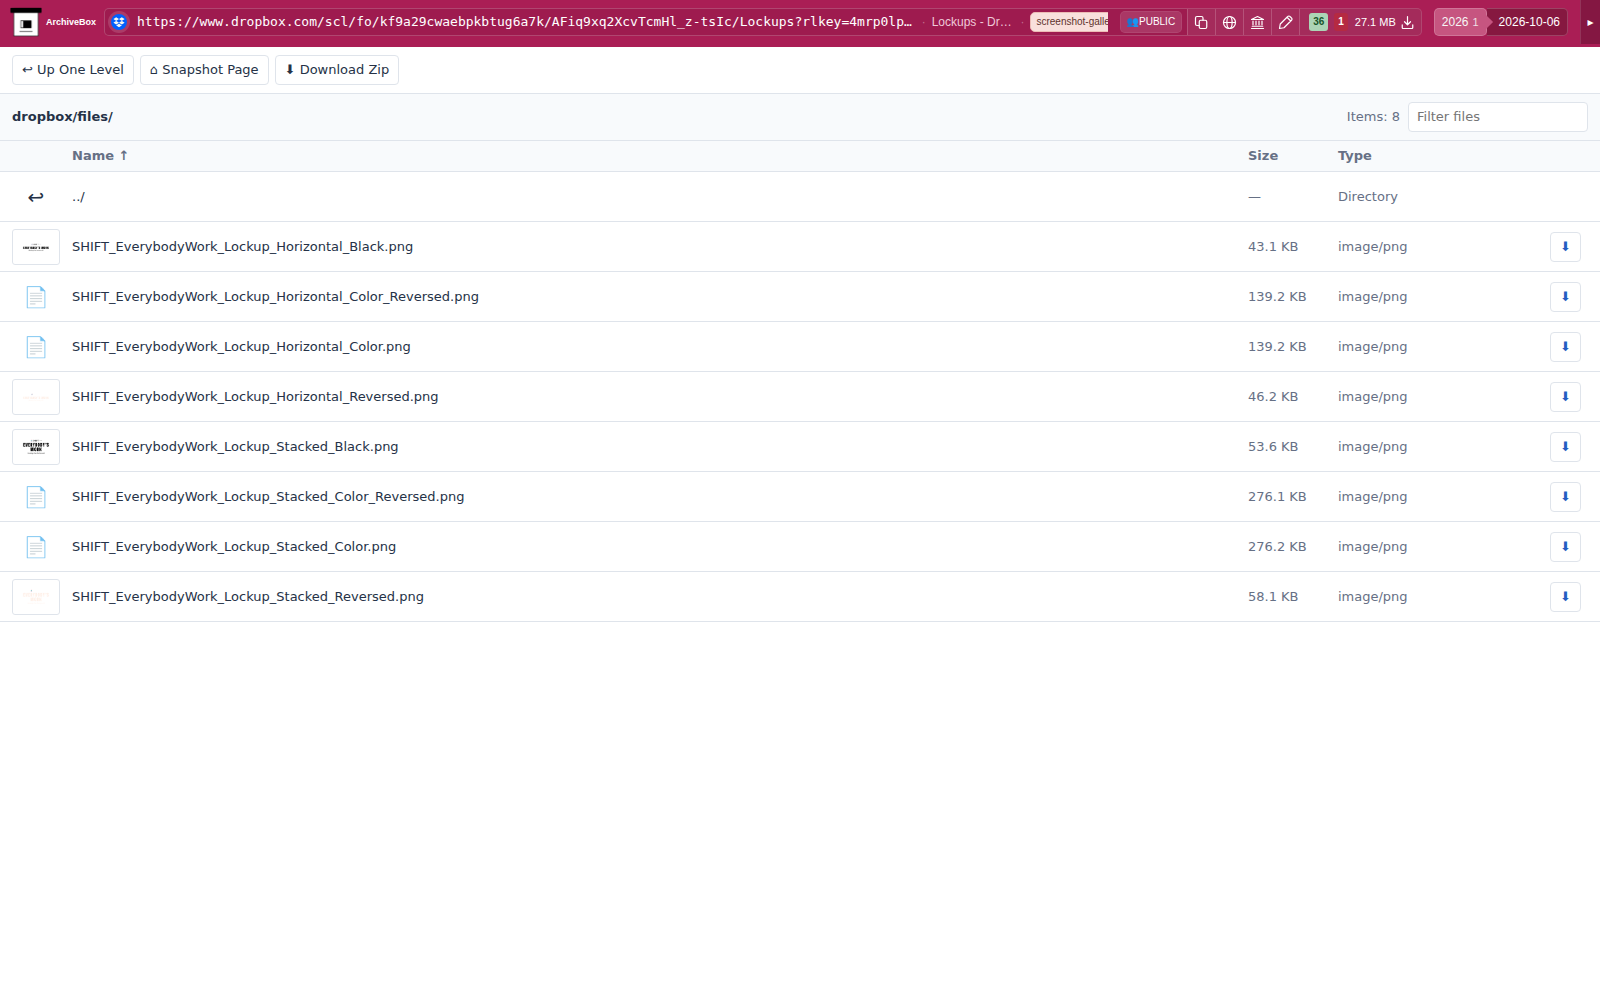
- 📄 Save Google Docs, Sheets, Slides, Google Drive, and Dropbox files. The new Google Drive plugin, Google Docs plugin, and Dropbox plugin export as ZIP, DOCX, XLSX, PPTX, CSV, PDF, SVG, and more. Supports both public & private docs using existing cookies, no separate OAuth setup needed. Automatically OCRs + full-text-search-indexes images PDFs, and other saved files with Liteparse too!

- 📱 Fewer broken images when replaying on a phone. The new Mobile Size plugin briefly visits a phone-width layout after saving desktop outputs, allowing you to view your saved pages nicely on a Mobile device even if the main capture was made in a dekstop browser.
- 🗂️ A better file explorer UI inside your snapshot cards.
- ⚡ Performance improvements to adding new URLs. Adding & viewing new URLs is now significantly faster even when the
/datadir is on slower networked storage. Large crawls with 1,000+ URLs are also significantly faster, and long-running captures use less memory. - 🗑️ Deleting 100+ snapshots no longer crashes. Snapshot deletion now runs in the background because deletion of many snapshots can be slow on remote storage. If file removal fails, the snapshot stays tracked for another attempt rather than disappearing from the database while its files remain behind.
- 🔐 Persona &
Cookies.txtfile fixes. Bugfixes around auth and cookie file path handling in some edge cases. - 🛠️ And more... Fixes improve SingleFile and WACZ downloads, PDF text extraction, and handling of cloud-folder links. Rescanning older archives recovers previously missing results, more cards are properly hidden with
noresultswhen they don't contain meaningful output
v0.9.71: UI fixes for small screens, performance and correctness improvementns
Changes since v0.9.70
- 📱 Cleaner snapshot card UI on narrow screens. Long tags and labels fit more gracefully in the public list and admin grid.
- ⚡ Faster browsing in large archives. Public snapshot pages render without waiting to count the whole collection, and reuse saved metadata instead of repeatedly querying each item. Totals may appear on a later reload while captures are running.
- 📊 Lighter live progress. Progress checks use read-only, indexed queries instead of performing filesystem and lifecycle work on each poll. Waiting for a tool's first result no longer burns a CPU core.
- 🔄 More reliable stops, restarts and runner takeover. Fix shutdown hangs while reaping child processes and honor interruptions during resumed startup. A displaced runner leaves captures available for its replacement to resume; an explicit user abort still seals that capture attempt.
- 🔗 Preserve apostrophes in imported URLs. Shared parsing now respects the surrounding text, Markdown, CSV or JSON format instead of cutting URLs off at an embedded quote.
- 🌐 More dependable browser captures. ArchiveWeb.page's helper stays in the background, and capture readiness checks continue to work when that tab is hidden. Browser-extension upload recovery reuses the existing hook index.
- 🛠️ Various Python and Node
abxpkgplugin auto-installation bugfixes.
v0.9.70: Performance improvements and bugfixes
Changes since v0.9.64
- 🛠️ Fix an upgrade bug that could leave the background runner using 100% CPU with nothing left to archive. Existing affected collections are repaired automatically during upgrade. #1892
- 🧠 Adjust parallel captures to the memory available on your server, using the memory consumed by actual captures to decide when to start more work.
- 🔐 Reduce TLSNotary's memory use by loading its extension only when needed and avoiding a second rendered copy of the page. Check available memory before proving, and stop the proof with a clear error if memory runs low. Clean up verification windows without closing your original page or unrelated tabs.
- 📦 Improve WACZ captures of pages that use service workers. If your app cannot play a WACZ, the viewer now offers an Open in browser button.
- 🔎 Fix search commands when no virtual environment is activated.
- 🔄 Stop unnecessary progress polling after opening a saved output, and fix occasional CLI startup failures during concurrent database activity.
- 📁 Fix folder and ZIP links for older snapshots whose saved files live directly in the snapshot directory.
- ⬆️ Fix startup after upgrading older 0.6.x collections that created their own migration files. #1891
v0.9.64: More compact UI on Snapshot detail and list pages
Highlights


- 🗂️ Much more compact snapshot detail page header and list view
- 🗃️ Fixed migrated snapshots failing to open, including archives created in non-UTC time zones.
- 📄 ArchiveResult admin page improvements, better output files summary in admin views
- 📚 Improved article text extraction that preserves original image sizes, fixed SingleFile to avoid re-capturing Chrome's PDF viewer
- 🖼️ Improved capture of pages with images still loading, and made failed or empty downloads and WACZ exports easier to spot.
- 🔎 Fixed archive searches failing to start after reindexing.
Historic Context on the Recent Filesystem Migrations
0.7.x -> 0.9.x is the first time we've ever changed the filesystem layout of the data/ dir, because we're now moving to a model where snapshots are separated on disk by the user/{username} that owns them. This move also allowed us to solve longstanding issues with large collection performance that were caused by storing 10k+ directories in a single snapshot directory, the new layout puts them in a tree under user>recordtype>date>origin>uuid, which can hopefully be stable for a long time and scale to trillions of entries.
There are two ways we could've handle this (potentially massive) filesystem migration for people's existing data coming from 0.7.x:
- lazily move files to new locations when they are first accessed (to avoid needing to do a huge slow migration all at once)
- eagerly move files during the updating process, or ask users to run a command that does it all at once (
archivebox update --migrate-only)
Initially I tried to do it lazily on first access, but it is really hard to predict the load characterestics of the server / decide when to migrate things without wild spiky performance issues. e.g. if you load a big list of snapshots and open them all at once, it can easily crash the server unless we build a whole system to manage load. After much tinkering I decided it was better to have users explicitly run a command to migrate everything at once, and to build a few branches into the UI code to check for both the old structure and the new structure temporarily until migrations finish.
Predictably this has led to some bugs and in increased complexity around URLs and deeplinks into specific snapshot content (e.g. you may have noticed the icons from the snapshot list view lead to 404s when clicked on old migrated data). I apologize for these issues if you've run into them, but trust that your data is still there, it's just a bug in the UI code deciding to check for old locations vs new locations. Please help report bugs and open Github issues if you encounter anything like that!
v0.9.50: CLI live progress fixes and progress
Changes since v0.9.36
- 🛠️ Fix crawl interruption, runner takeover, and Ctrl+C handling; drain active hooks cleanly when stopping.
- 🕷️ Fix crawl limits, abort handling, and replay behavior.
- 📦 Verify bundled hooks and their dependencies before promoting releases to PyPI and Docker.
- ⬆️ Update the downloader and plugin dependencies, including
abx-dl1.13.27.
v0.9.36: ⭐️ MAJOR RELEASE - TONS OF IMPROVEMENTS
ArchiveBox v0.9 is now released. 🎉
It's been a long time since our last major release back in 2024!
Thanks for hanging in there, but I promise this release was worth the wait!
📖 Read the full Announcement Post
↗️
✨ The big changes
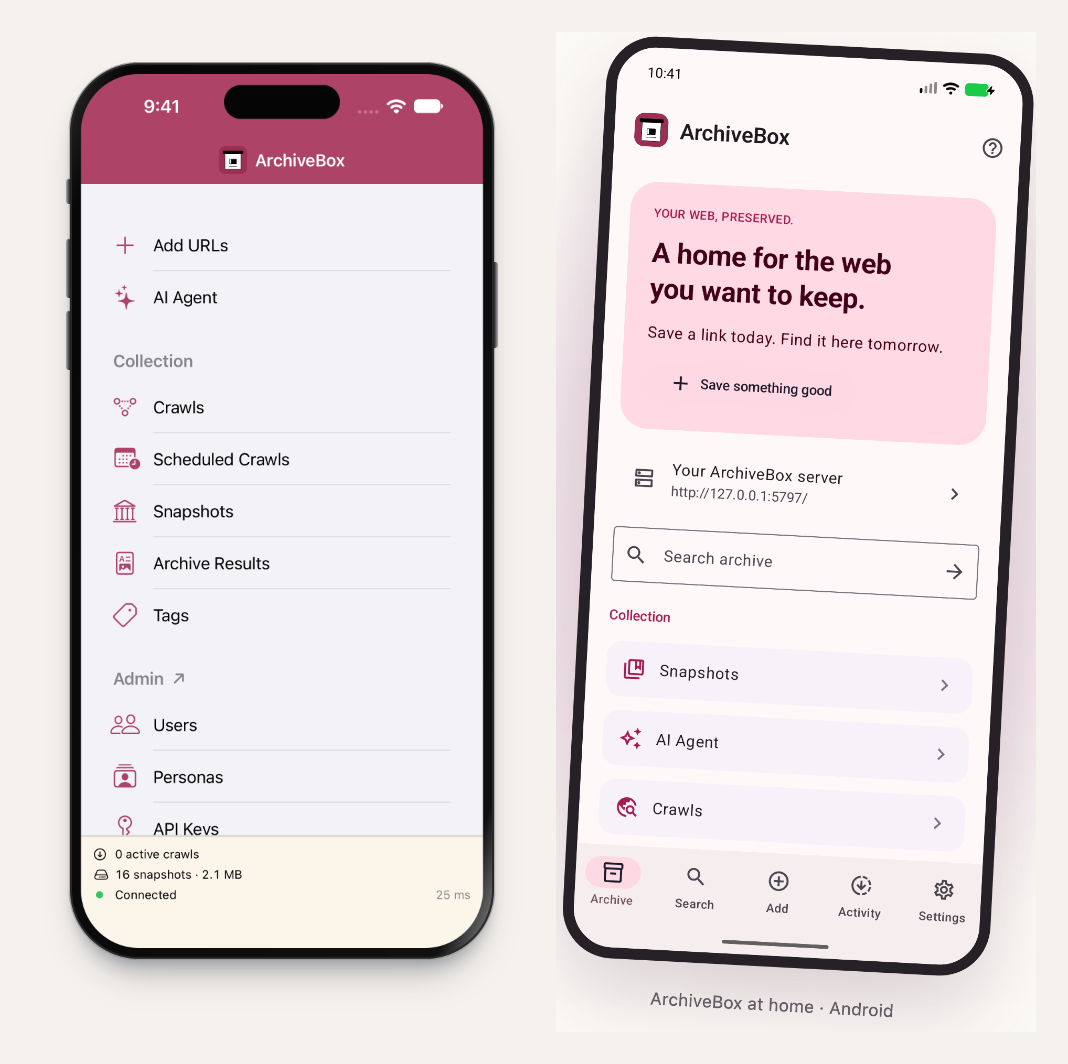
- 📱 NEW Native Mobile & Desktop Apps: iPhone / iPad / Android | macOS / Windows / Linux
- 🗂️ Redesigned output viewers: beautiful new viewers for article text, extracted video/audio, metadata + more
- 🧭 Vastly improved browser extension: import bookmarks/history, uploads local screenshot & MHTML
- 🐘 PostgreSQL support: SQLite remains the default, but we caved to demand and finally added PostgreSQL
- 🗓️ Scheduled crawls in the UI: schedule recurring import jobs directly from the UI, all in one Docker container
- 👤 Personas: archive sites logged-in using cookies & settings synced from extension, CDP, or local browsers
- 🤖 AI Tools: new MCP server, SKILL.md, and built-in agent (opencode) that can handle custom archiving tasks
- 🔏 Bulletproof chain-of-custody: new merkle hashes, TLSNotary attestation, and OpenTimestamps integration
- ⬇️ A new standalone oneshot CLI:
abx-dluses the same plugins without needing a full ArchiveBox server
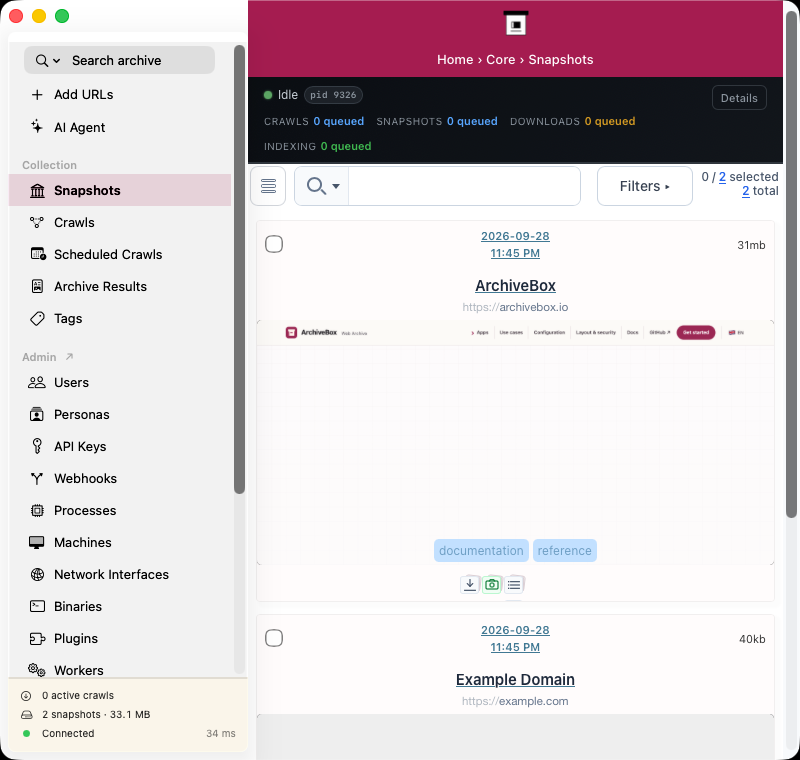
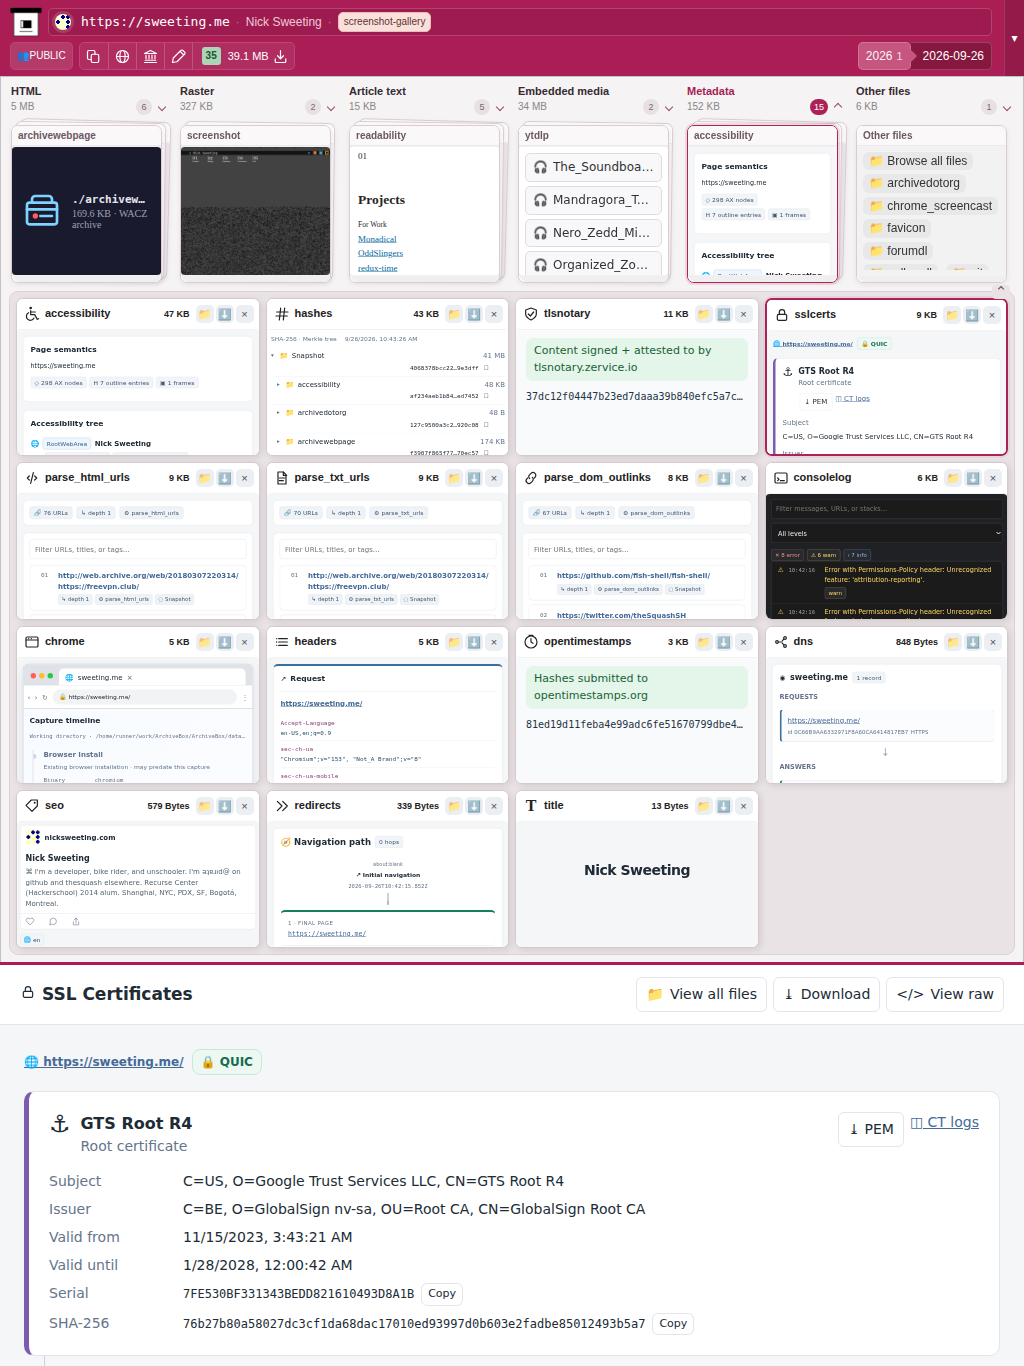
🗂️ More useful saved pages
- Responsive layouts across phone, tablet, and desktop.
- Expandable output stacks group related capture formats together.
- Article and document readers for extracted text, including PDF extraction outputs.
- Media galleries and players for images, audio, video, and captured browser responses.
- Repository previews with a file browser and rendered README.
- Readable metadata views: redirects, headers, DNS, certificates, accessibility trees, browser activity, and console logs.
- View raw, download one output, browse all files, or download a snapshot ZIP.
🛠️ More ways to automate it
- Expanded REST API for crawls, snapshots, results, tags, users, tokens, and operational state.
- Pipeable JSONL CLI commands to create, read, update, delete, and enqueue model records.
- Webhooks for integrating archive events with other systems.
- Standalone
abx-dlfor one-shot downloads using the same plugin library, without a collection database or web server.
⬆️ Upgrading from 0.7.x
Make a full offsite backup of your archive before proceeding, and be aware 0.9 will move some data/ dir files to new filesystem locations. Filesystem migration is done lazily, and can be interrupted / resumed at will.
- Stop the old server.
docker compose down - Back up the entire collection: database, configuration, archive files, and browser Personas. A database-only backup isn't enough.
- Install 0.9.x following the instructions for your platform. See https://archivebox.io
- Run
archivebox initto upgrade the database. Migrations can take minutes to hours depending on db size. - Run
archivebox update --migrate-onlyto start migrating filesystem data to the new locations (if this step is skipped, it will happen lazily on first access and may slow down the UI) - Keep the backup until you've verified the final setup looks good!
For Docker Compose, update your docker-compose.yml first, then:
docker compose run archivebox init
docker compose run archivebox update --migrate-only
docker compose down --remove-orphans
docker compose up -d
Upgrade Notes
- We now recommend >=
2GBRAM minimum, though it does still work (slowly) on smaller systems. - Custom config should be moved out of
docker-compose.ymlenvironment:intodata/ArchiveBox.conf: otherwise you wont be able to edit it via the new built-in Machine config admin UI - Python >=3.13+ is now required if installing on bare metal.
- New filesystem layout for
data/archive/snapshot directories. Files will get auto-migrated on first access.
data/archive/{timestamp}->data/archive/users/{username}/snapshots/YYYYMMDD/example.com/{uuid} - New DNS, SSL, and HTTPS serving requirements: For better security, wildcard subdomain support was added to isolate archived JS, but new DNS+TLS settings are needed (
BASE_URL+SERVER_SECURITY_MODE). - PostgreSQL support is added, ask your agent to help migrating data from SQLite if desired.
Upgrade guide · Merging collections · 🐛 Report an issue
A lot of what we promised in The Future of ArchiveBox is now here!
Full Changelog: v0.7.4...v0.9.36
v0.9.31-rc: New abx-dl runtime, split-out plugin ecosystem, resumable migrations, and isolated snapshot replay

Warning
This is a pre-release for the upcoming ArchiveBox v0.9.x line. The latest stable release is still v0.7.4. Please test on a backup first and report regressions before using this for a production collection.
v0.9.x is a large architectural upgrade from v0.8.x: plugin execution has moved out into a standalone plugin ecosystem, archiving runs through the new one-shot abx-dl CLI, and the old pluggy path has been replaced by an event-driven, append-only-log architecture designed to support future browser-extension capture and p2p sync.
⬇️ RC Instructions: use the :dev Docker image with the repo docker-compose.yml
git clone https://github.com/ArchiveBox/ArchiveBox && cd ArchiveBox
ARCHIVEBOX_IMAGE=archivebox/archivebox:dev docker compose up -d
Highlights
-
🔌 New plugin system split out into
abx-plugins
The extractor/plugin catalog now lives ingithub.com/ArchiveBox/abx-plugins, with per-plugin config, dependencies, hooks, docs, and install metadata. -
⚡ New one-shot CLI powered by
abx-dl
ArchiveBox now builds on the standalone downloader atgithub.com/ArchiveBox/abx-dl, so plugin-based archiving can run inside ArchiveBox or independently as a focused CLI. -
🧱 No more
pluggy; new event-driven runtime
v0.9.xreplaces the oldpluggy-style in-process plugin system with an event-driven, append-only-log flow. This gives us cleaner resumability, auditability, and a path toward future browser extension capture, distributed workers, and p2p sync. -
🗃️ Safer data layout and migrations
The new layout keeps user-owned snapshot/crawl data underdata/archive/users/{username}/..., creates crawl records for migrated snapshots, and preserves legacy ArchiveResult data instead of rediscovering everything from slow filesystem scans. -
🖥️ Improved browser isolation and output serving
Chrome-based extractors now use crawl-scoped browser sessions, cleanup cloned profiles after each crawl, and serve snapshot outputs throughweb.archivebox.io/snap-*.archivebox.iostyle isolation for safer replay. -
🧭 Tons of UI, CLI, REST API, and database improvements
Faster snapshot/admin list views, better live progress visibility, improved ArchiveResult detail pages, cleaner REST API paths, and more durable Process/Crawl/Snapshot database state.
What's Changed
- 🔌 Extractor plugins moved into
abx-plugins, with generated plugin docs atarchivebox.github.io/abx-plugins. - ⚡ Archiving execution now goes through
abx-dl, which can also be used directly:uvx abx-dl --plugins=title,screenshot,singlefile 'https://example.com' - 🧾 Runtime execution now writes structured append-only JSONL records for Crawls, Processes, Snapshots, and ArchiveResults.
- 🔄 Migrations now preserve legacy
Snapshot,Tag,ArchiveResult, and filesystem output data across0.7.x/0.8.x→0.9.xupgrades. - 📁 Heavy crawl/snapshot data stays under
data/archive/users/...for Docker volume compatibility. - 🌐 Added subdomain-aware replay for public web, admin, API, and isolated snapshot hosts.
- 🔒 Added stricter public/admin/API separation and safer default demo deployment options, including disabling public add flows by default.
- 🧩 Browser extractors now share crawl-scoped Chrome sessions and centralize profile cleanup / lock handling through
chrome_utils.js. - 📸 SingleFile, screenshot, DOM, readability, media, git, gallery, forum, and other extractors now run as plugin hooks with explicit outputs.
- 🛠️ Improved
archivebox add,archivebox run,archivebox update,archivebox version,archivebox status, and dependency install flows. - 🚀 Docker image now includes the new unified runtime stack, with Sonic search managed inside the main container.
- 🧪 Validated against large migrated collections, including the public demo dataset, with resumable migration behavior and preserved DB/file outputs.
Helpful related projects and resources:
SingleFilefor self-contained HTML capturesyt-dlpfor media extractiongallery-dlfor gallery/media sitesDjango Ninjafor the REST APISonicfor lightweight search indexing
Full Changelog: v0.8.5-rc...v0.9.31-rc
v0.7.4: Updates for Docker container's SingleFile, YT-DLP, Chrome, Node, gosu, and other dependencies
This is an update for the archivebox/archivebox:latest Docker container's internal dependencies and the 0.7.x package metadata/lockfiles.
- chromium
v147(viaplaywright==1.59.0) - Chrome for Testing version validation fixed for Playwright Chromium builds
- Node.js ->
v24.15.0 - gosu ->
v1.19 - yt-dlp ->
2026.03.17 - single-file ->
v2.0.83 - curl, wget, git, ripgrep, ffmpeg
- Python dependencies bumped (except for Django, which is still limited to
>=3.1.3,<3.2)
Run archivebox version after updating and make sure any manually-installed system dependencies are up to date. Always back up your archive before upgrading.
Tip
All new development work is happening over in the v0.9.x dev branch.
Full Changelog: v0.7.3...v0.7.4
