How autonomous agents turn static knowledge graphs into living Context Graphs that remember decisions, user intent, and operational history
How autonomous agents turn static knowledge graphs into living Context Graphs that remember decisions, user intent, and operational history
Local and global variants, Fisher estimation, epsilon-ball sampling, and log-space stability, with PennyLane code and a time-series experiment.
A step-by-step guide to transition matrices, the Chapman–Kolmogorov equation, and stationary distributions, built around a three-state writing example.
Quality and token alerts were early signals for 38% of agents and errors for about 1%, so monitoring should start with quality, cost, and latency.
On 200 ToolRet questions and up to 3,794 tools, BM25 ran about 40x faster than BGE-large on just a CPU, and full tool docs made it the best setup tested.
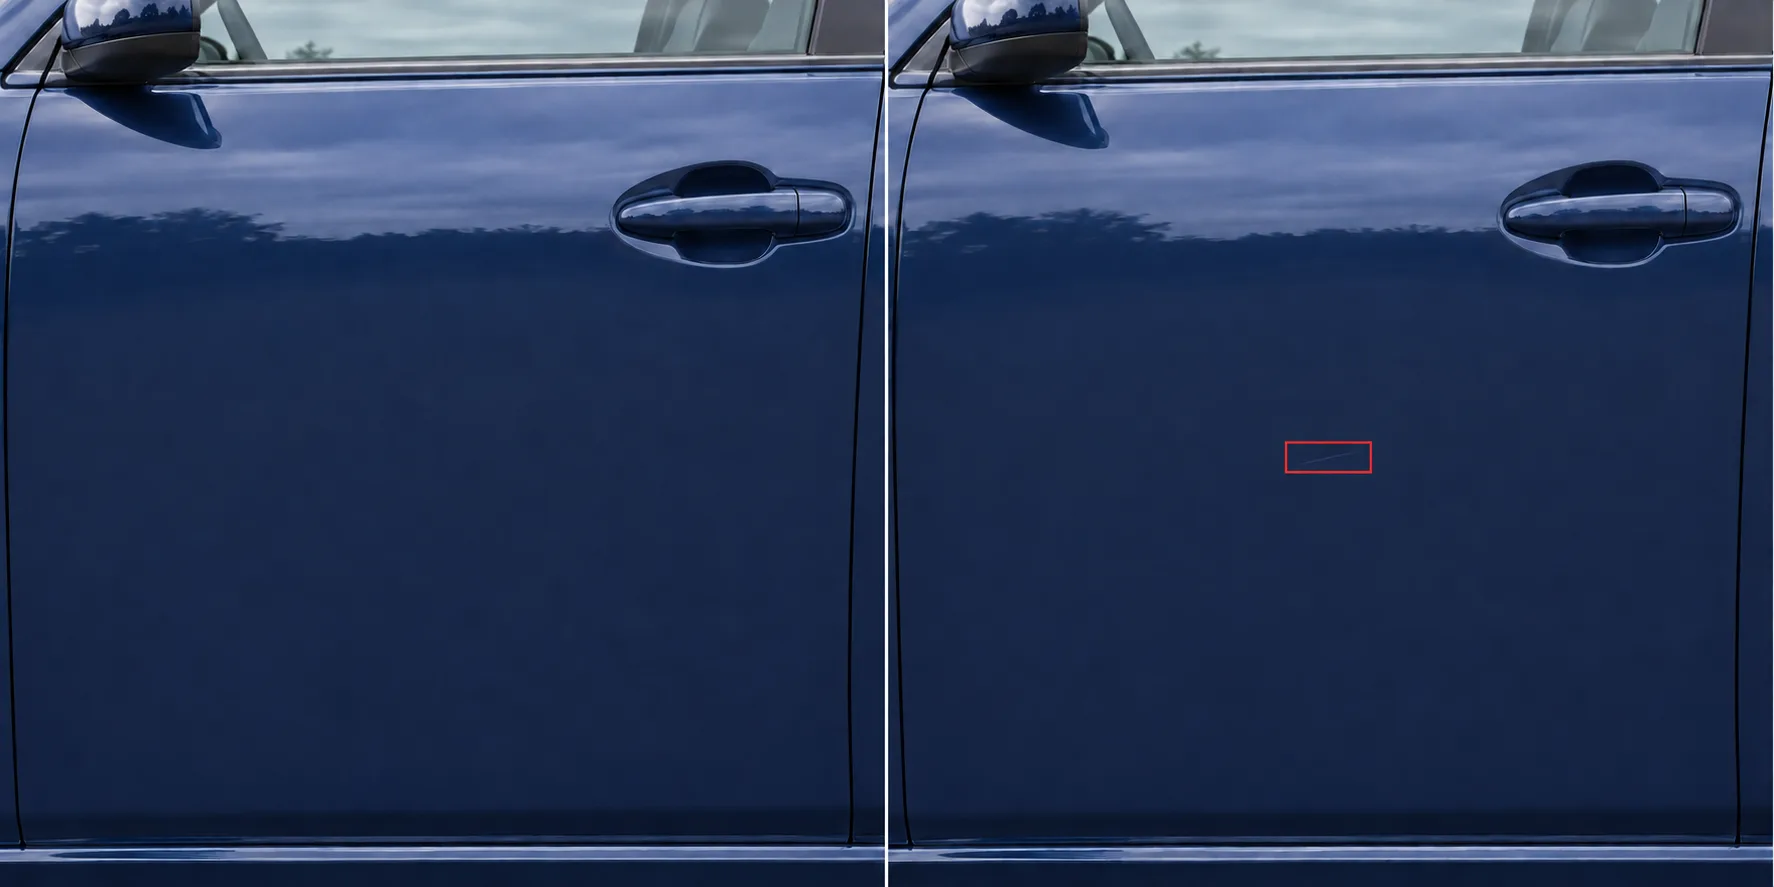
Practical code for classifying fabric against reference photos, scoring product sharpness, cropping shipping labels, and spotting subtle car damage.
A PhD student in ML and ecology on why faster code, experiments, and drafts don't fix data with a backstory, and three predictions for how labs will change.
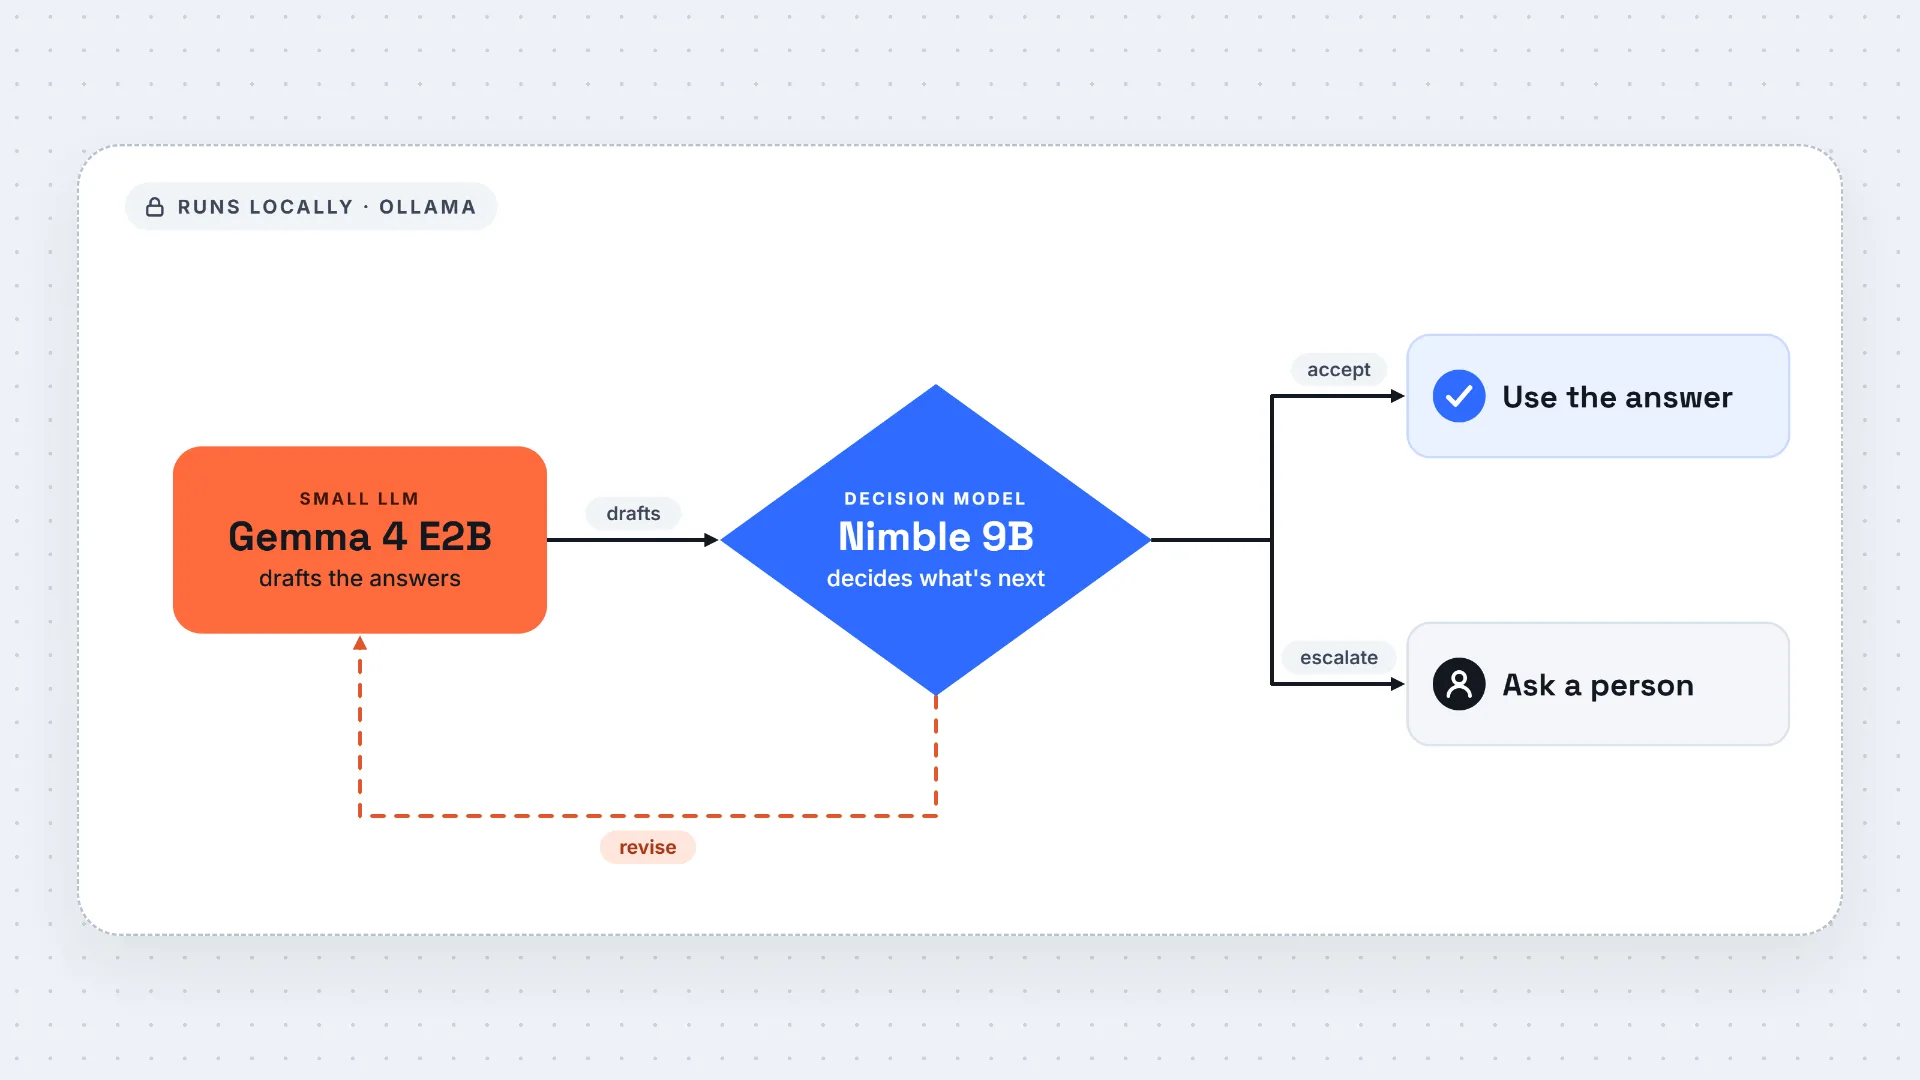
Gemma 4 E2B drafts the replies, Bespoke Labs' Nimble 9B picks accept, revise, or human review, and only flagged questions get a focused retry.
A reproducible test of BM25, embeddings, and parent documents shows why author-written evals overrate search, and why answer position in context matters.
Across 2,312 planted faults the study also surfaced four real library problems, from a Windows data-loss bug to README examples that do not work as written.
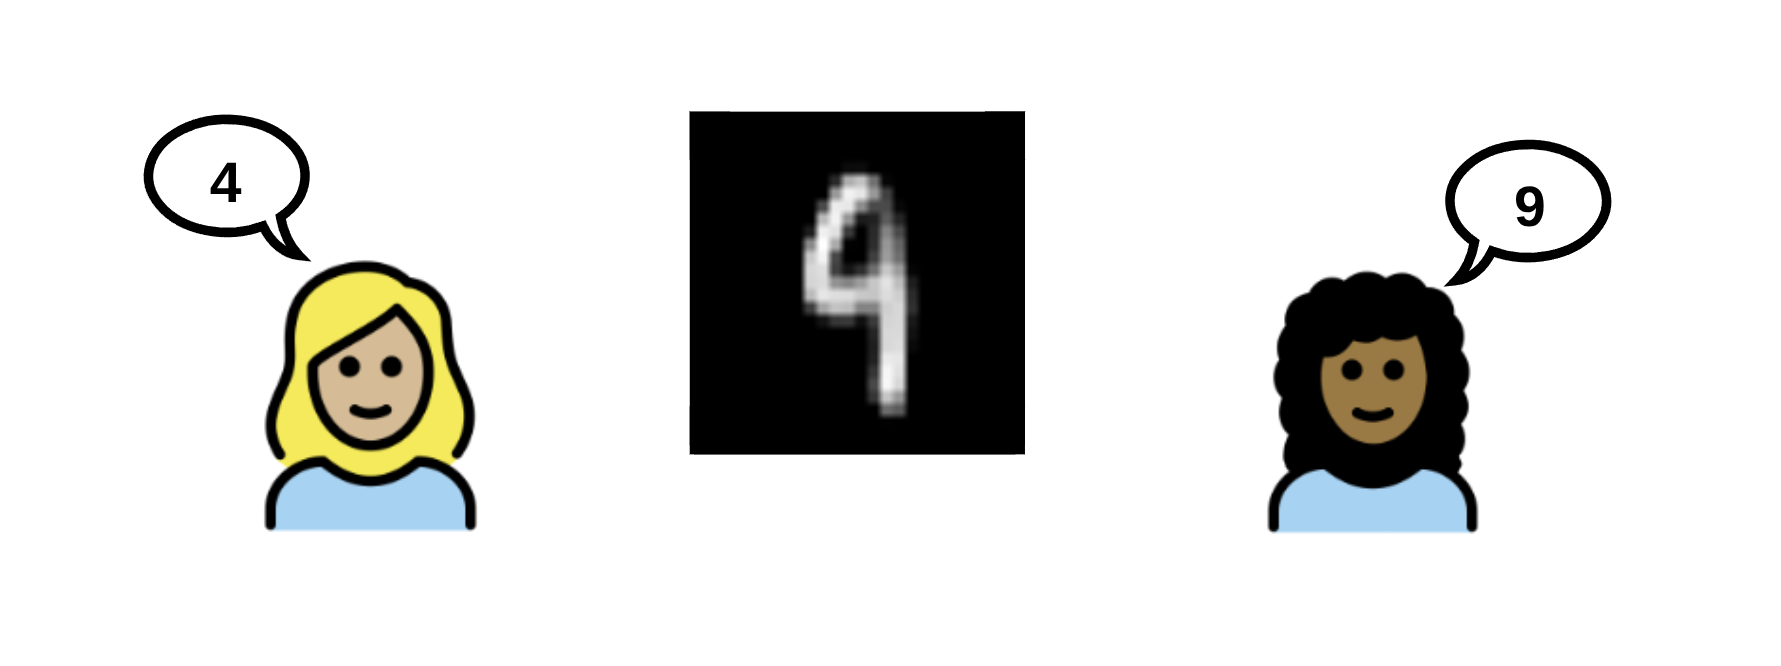
Annotators marked each MNIST and Mukhoti digit yes, no, or unsure, producing image-level soft labels and uncertainty scores.
Local and global variants, Fisher estimation, epsilon-ball sampling, and log-space stability, with PennyLane code and a time-series experiment.
A step-by-step guide to transition matrices, the Chapman–Kolmogorov equation, and stationary distributions, built around a three-state writing example.
Quality and token alerts were early signals for 38% of agents and errors for about 1%, so monitoring should start with quality, cost, and latency.
Practical code for classifying fabric against reference photos, scoring product sharpness, cropping shipping labels, and spotting subtle car damage.
Gemma 4 E2B drafts the replies, Bespoke Labs' Nimble 9B picks accept, revise, or human review, and only flagged questions get a focused retry.
Across 2,312 planted faults the study also surfaced four real library problems, from a Windows data-loss bug to README examples that do not work as written.
Sorting through the good, bad, and ambiguous aspects of vibe coding
Don't miss our most-read and -shared stories of the past month
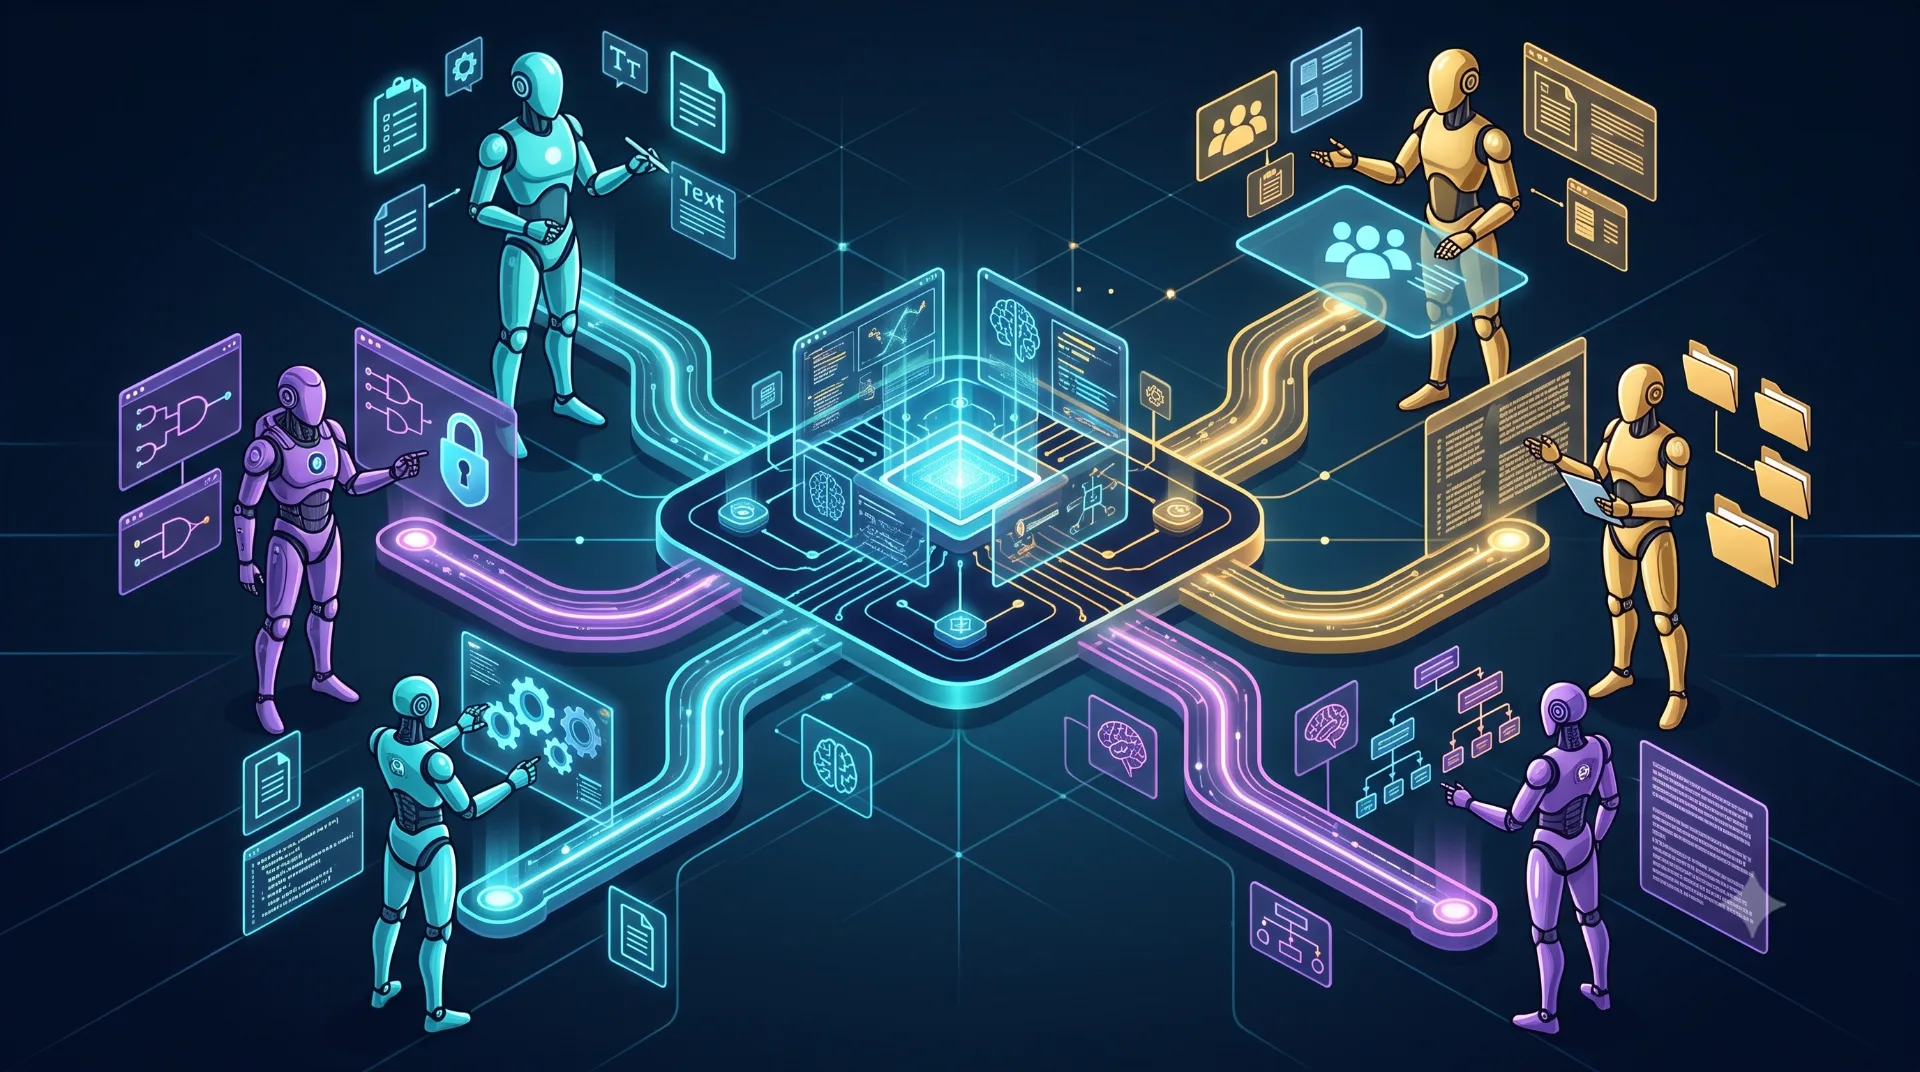
Beyond basic ReAct loops: six production-oriented architectures for building autonomous, reliable, and scalable LLM agents.
How statistical moments connect the mean, the variance, and higher powers of a distribution
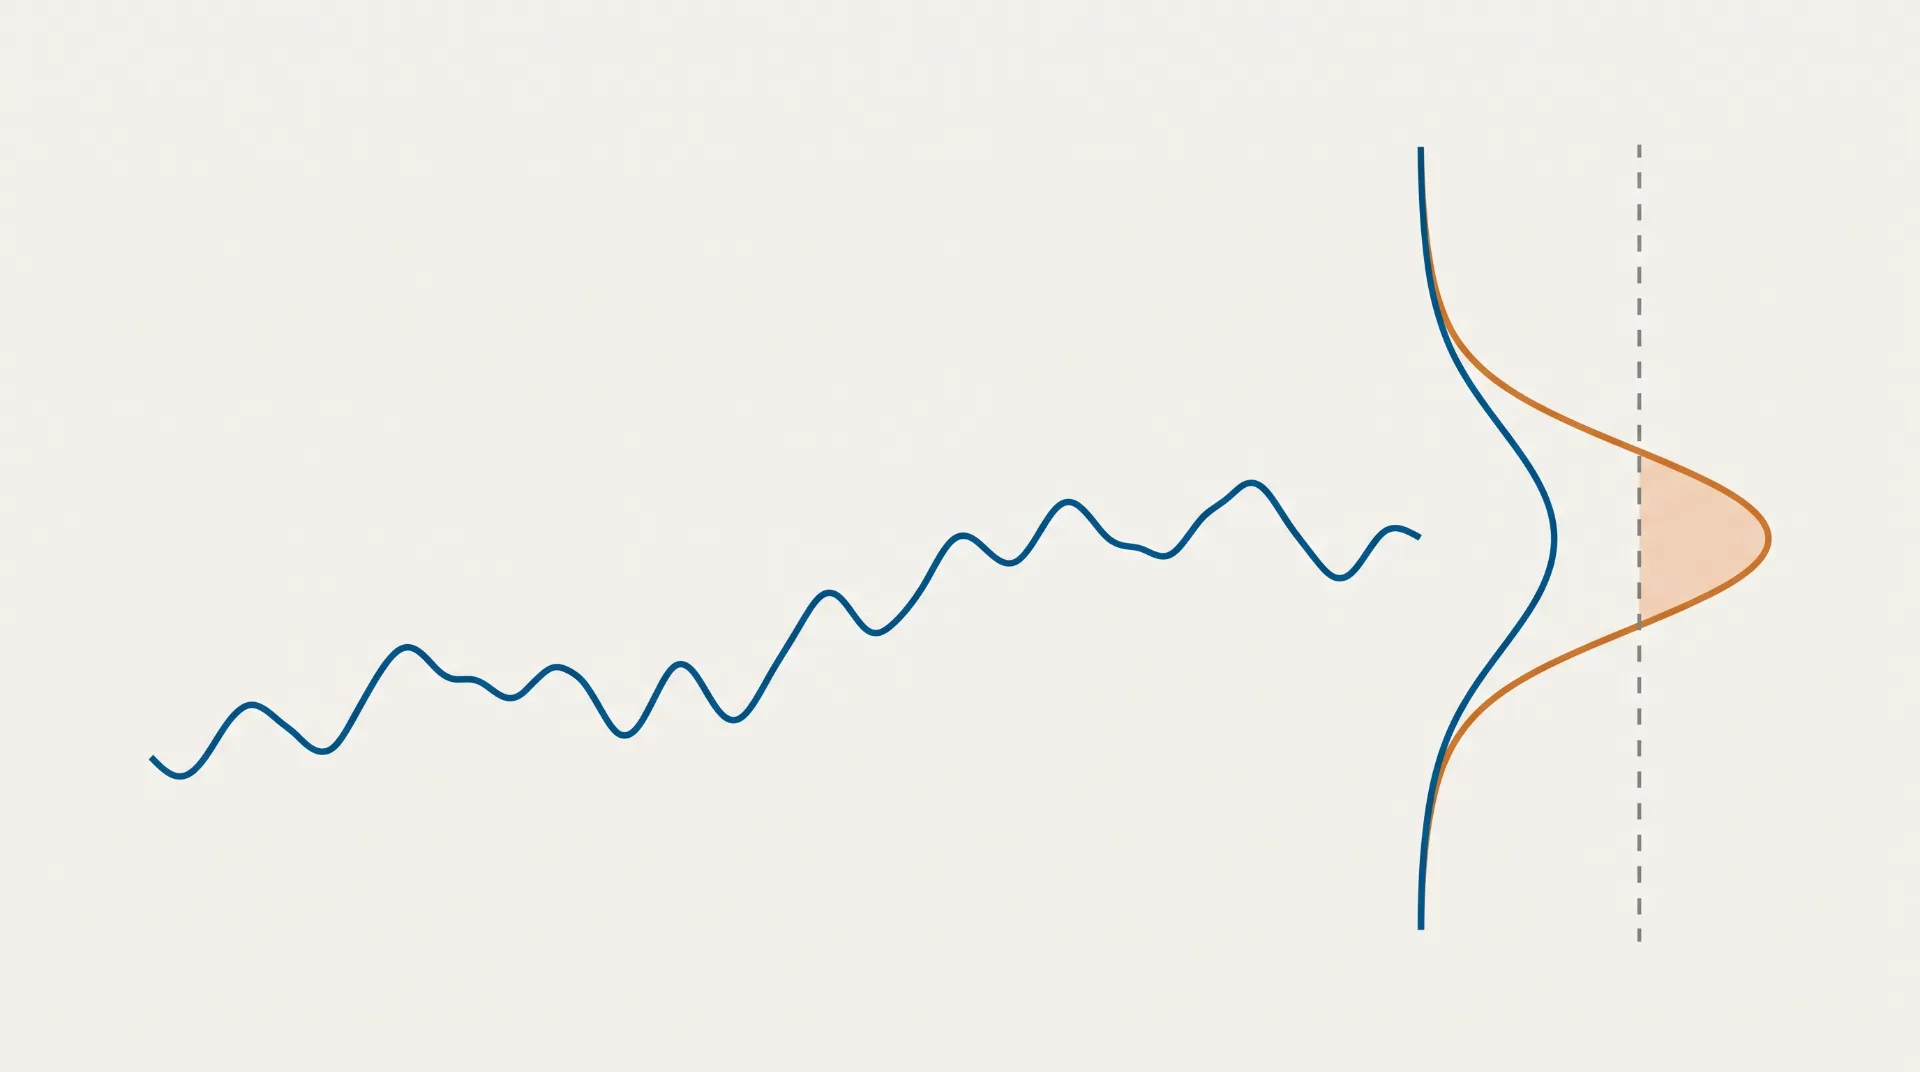
First in a series on probabilistic forecasting for physical signals. Next: what happens when you roll the forecast forward more than one step.
When Codex is the right shape for the problem, when Claude Code is, and how I split 5 specialist agents between them on dense AI capacity work.
Why the skill-inflation panic is aimed at the wrong thing, and what it costs to make agent knowledge a build artifact instead of a file.
A real Weave project that regression-tests three OpenAI models against the exact reply format your app depends on.